 ComingUp
RoutineArc — on-device AI planner for Android
Android day planner with on-device AI — no backend, no per-user AI costs.

Is this your project? Ask us to take it down
Gallery
About
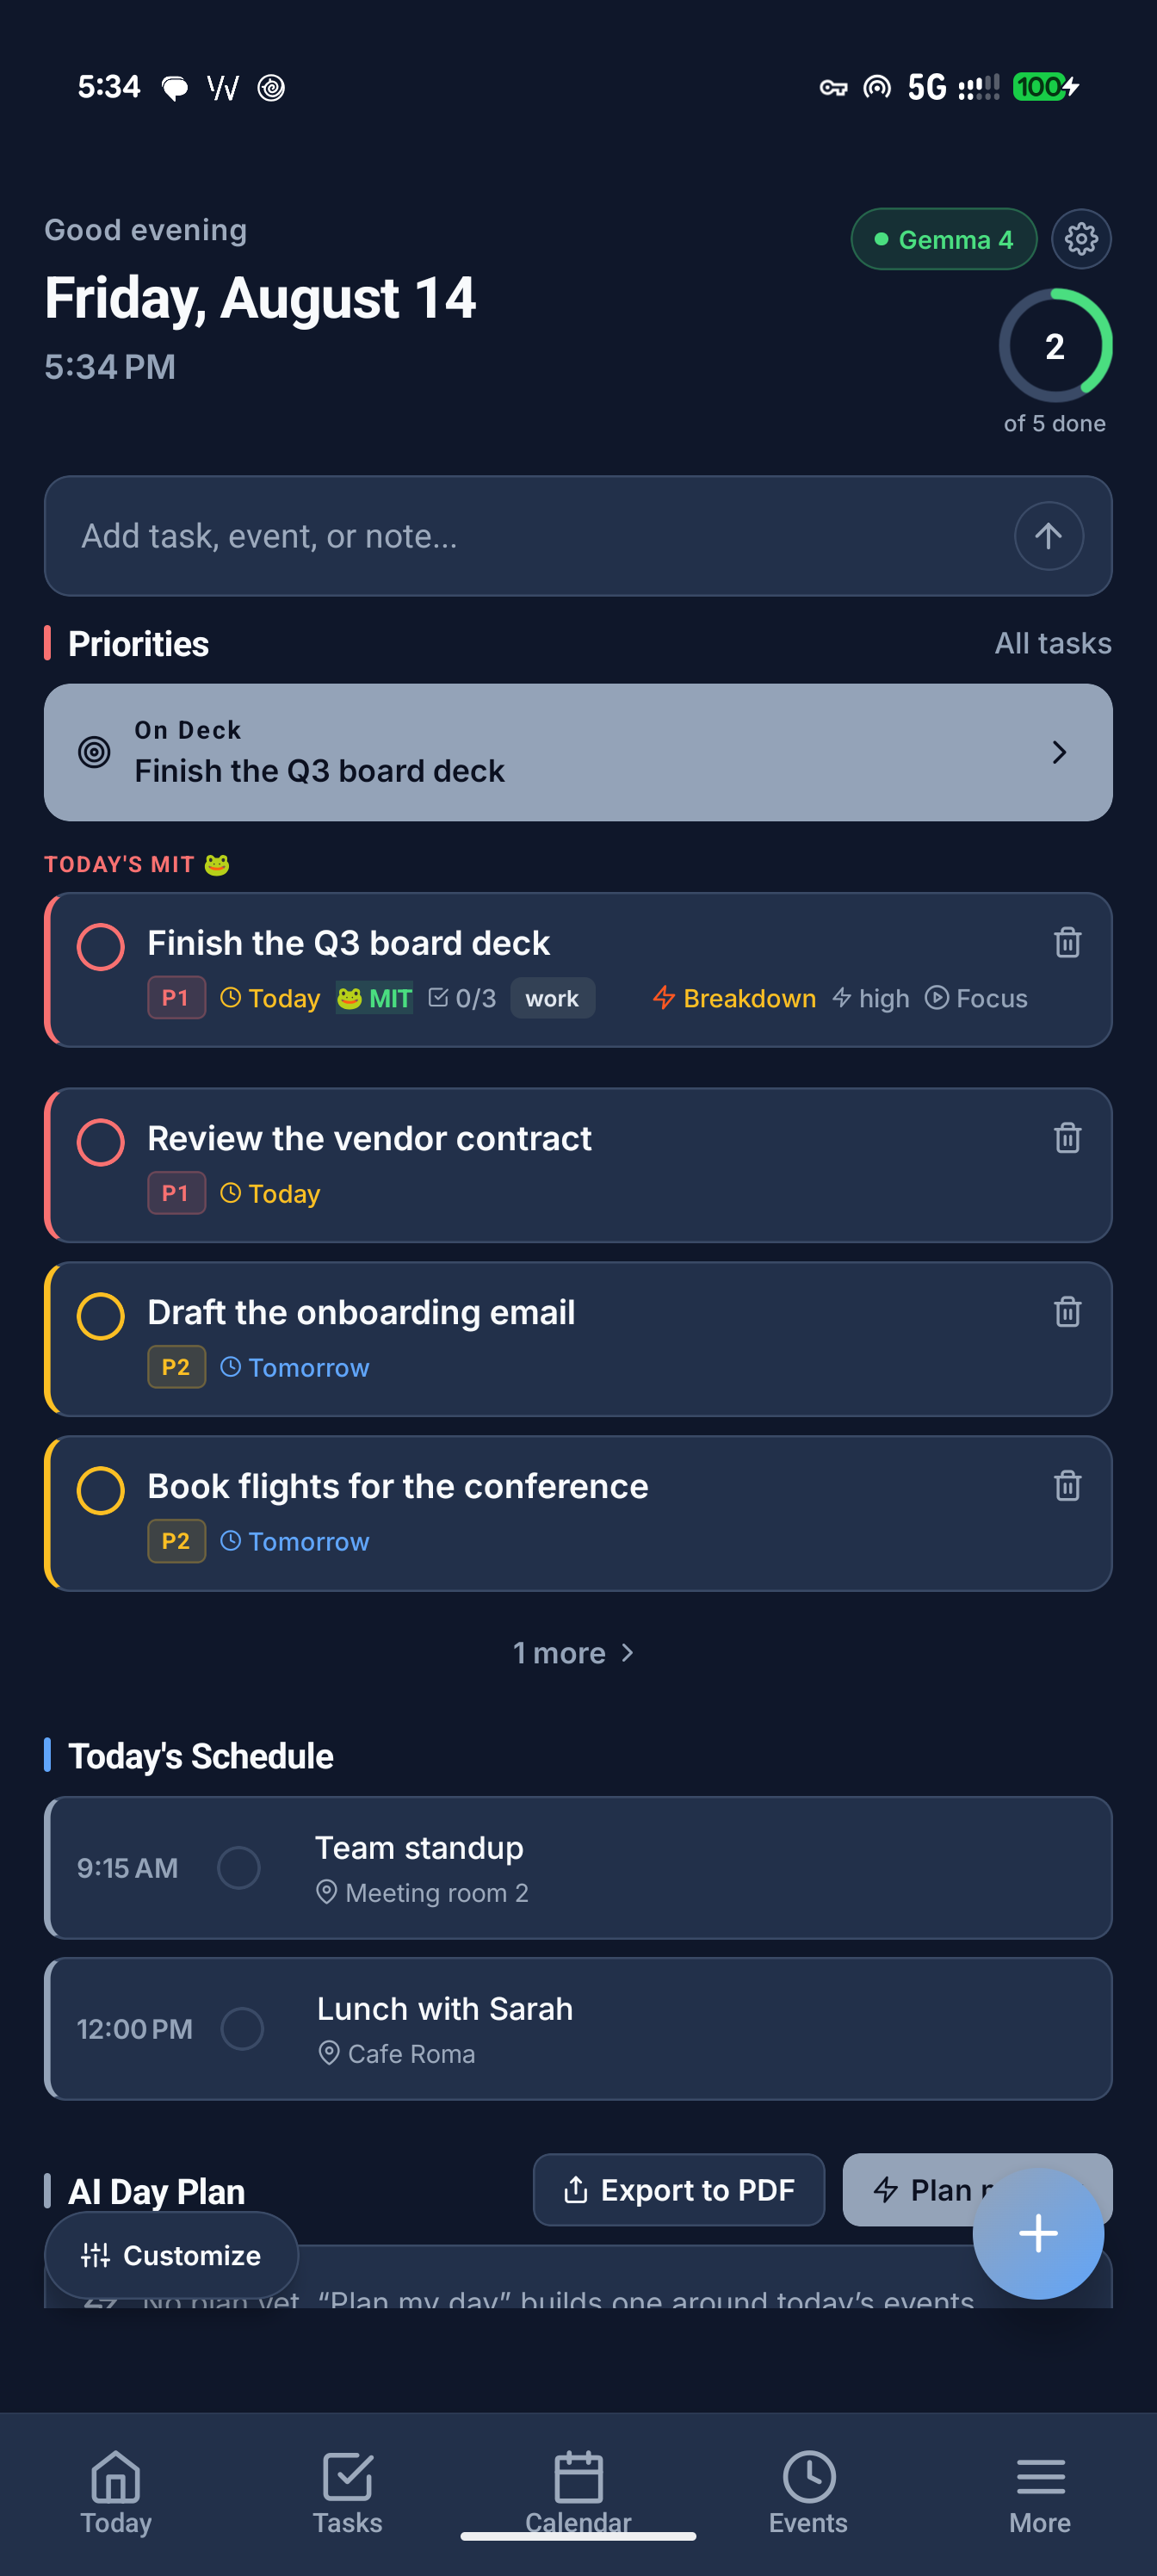
RoutineArc is a working Android productivity app built around one idea: the AI
should run on your phone, not on someone else's server.
It is not a finished product. It is a substantial, tested codebase that runs on
real hardware and still has a known list of work to do before it could ship —
that list is at the bottom of this listing, not hidden.
You capture the way you think — type "dentist tomorrow at 3pm", say it out loud,
or photograph an appointment letter — and it becomes a properly dated task or
event with priority, duration, location and repeat already filled in. It then
plans your day around the calendar events you already have.
THE ENGINEERING THAT MAKES IT WORTH BUYING
Three interchangeable AI backends sit behind a single interface, and the user
picks which one runs. All three are scored against the same 27-case, 91-field
capture fixture:
• Gemini Nano — uses Android's built-in AICore, nothing to download.
91/91 at best; 88–89/91 under sustained use, because AICore rate-limits
repeated calls and the run retries.
• Gemma 4 E2B — one-time 3.68 GB download, runs on the Tensor G5 NPU.
90/91, verified on device. Recorded at 91/91 earlier; re-measured across four
runs on 15 Aug 2026 it scored 90/91 every time, always losing the same field.
• Rules engine — needs nothing at all.
91/91, verified in the test suite. Deterministic, so it is reproducible in CI
rather than needing a phone; individual captures were also confirmed on device.
That third one is the commercially important one. The app still works on phones
that can run neither model, with no cloud fallback — so there is no inference
cost per user, ever, and no server to keep alive.
Because there is no backend, there is no hosting bill and no scaling work.
Everything lives in SQLite on the device. The app makes no network calls of its
own except an optional address lookup that ships switched off; choosing Gemma 4
downloads the model once, and tapping "Navigate" hands an address to Google Maps.
WHAT'S IN IT
Capture by typing, voice, or photo with on-device OCR · AI day planning around
real events · Eisenhower matrix with drag-to-reprioritise · focus sessions
(Pomodoro, timer, stopwatch) · habits with streaks · weekly review, evening
triage and a "Keep It Honest" screen · saved places with "leave by" travel times
· work schedules and shifts · recurring tasks · home-screen widgets · Wear OS
companion · PDF export · backup, restore and CSV import · a built-in user guide
that exports itself as a PDF.
28 screens.
MEASURED, NOT ASSERTED
Every figure below came off a real device or a real build, and the method is
recorded in the engineering audit inside the repo:
• Capture accuracy — the three scores above, against a shared fixture.
• Cold start 251–287 ms on a Pixel 10 Pro XL, force-stopped between runs.
• Scroll jank 0.00% on the calendar at 30 tasks and 8 events; no missed vsync
on any screen measured.
• Download size about 61 MB per device on arm64, built as an App Bundle.
• 2,141 tests across 167 suites, running in about 15 seconds from a clean clone.
Where an earlier claim turned out to be wrong, it was corrected rather than
quietly dropped — the audit records the withdrawn ones too.
BUILT TO BE HANDED OVER
• 2,141 tests across 167 suites — including the data layer tested against a real
SQLite engine, and a smoke test that mounts every one of the 28 screens.
• A custom Kotlin native module exposing Gemma 4 on the Tensor NPU through
LiteRT-LM. This was the hard part.
• A measurement harness that scores capture accuracy against a fixture, so any
future change to the AI can be proven not to have regressed it.
• A guided code tour written for whoever owns it next: where to start, why the
unusual parts are the way they are, and the traps that would otherwise cost a
day each.
• An engineering audit recording what was measured, what was fixed, and what was
deliberately left alone.
TECH STACK
Expo SDK 54 · React Native 0.81 · TypeScript 5.9 · expo-router · SQLite
(expo-sqlite) · ML Kit GenAI (Gemini Nano) · ML Kit text recognition (OCR) ·
LiteRT-LM + custom Kotlin Expo module (Gemma 4 on NPU) · Jest
TRAFFIC AND REVENUE
None. Never published to Google Play. No users, no downloads, no revenue. This
is a working codebase with known remaining work, not a running business.
WHAT'S INCLUDED
Full source repository (private GitLab, access granted on agreement) · the custom
Gemma NPU native module · 2,141 tests · capture measurement fixtures and harness
· in-app user guide and its PDF generator · guided code tour, engineering audit
and release documentation · app icons and branding · copyright assignment on
completion.
KNOWN ISSUES AND LIMITATIONS — DISCLOSED UP FRONT
• Release builds are currently signed with the debug keystore, so a real signing
key must be configured before Play submission. Documented; roughly an hour.
This is the only hard blocker to publishing.
• Tested on one phone model. All device verification was done on a Pixel 10 Pro
XL, plus one Android emulator used to confirm the app degrades correctly where
no AI hardware exists. It has not been run across a range of screen sizes, OEM
skins or Android versions. minSdk is 26.
• The Android build directory is not in the repo. A fresh clone runs
`expo prebuild`, then re-applies two documented manual edits: the
uses-native-library declarations that give Gemma 4 access to the NPU, and a
signing key. The README covers both. Budget an hour before your first release
build.
• The universal APK is 305 MB because it bundles four CPU architectures.
Building as an App Bundle instead delivers about 61 MB per device on arm64,
with no code change — measured from the built bundle, not estimated.
• Photo capture scores 31/32 on the image fixture where text capture scores
90/91. One field remains: on a patient-portal screenshot the model names the
clinic in the notes rather than the location field. The other five fixtures
pass completely.
• Two written and tested modules are not wired up: share-sheet intake, and
location-based reminders. Both need native edits in the generated Android
directory; the audit explains why that was deferred rather than risked.
• The Wear OS companion sends data but has not been verified against a physical
watch.
• Development was AI-assisted. A large amount of this code was written with an AI
coding assistant, under my direction and review. I am saying so up front
because you would reasonably want to know. The answer to the obvious next
question — whether it is held together — is the part I would rather be judged
on: 2,141 tests, a data layer exercised against a real SQLite engine, a smoke
test that mounts all 28 screens, and AI accuracy measured against a fixture on
real hardware rather than asserted. The engineering audit in the repo lists
what is still open, including the items above.
A note on the screenshots: a few carry small grey rectangles. Those are
deliberate redactions covering my own real tasks and appointments — the shots
were taken on a device in daily use. They are not UI defects.
Comments (2)
zero per-user ai costs is smart, which model runtime
running inference locally is the right call for privacy
Related Products
iZoneMedia360 .com – Trusted Hub for Startup & Tech Innovation Trends
An SEO-ready content blog focused on digital media, tech, and business topics wi
Kanso Rental Property Management System
High-end rental property management tool with little competition + large market
Aakhya.AI - Intelligent Cloud Cost Optimization Platform
Intelligent Cloud Cost Optimization Platform
Workalizer
Google Workspace AI-driven insights to improve productivity and performance
e-mail.dev
Turnkey email validator Micro-SaaS on a premium .dev domain.
The Real World of Autism
Globally raising Autism Awareness and Monetizing all parties