 ComingUp
Gallery
About
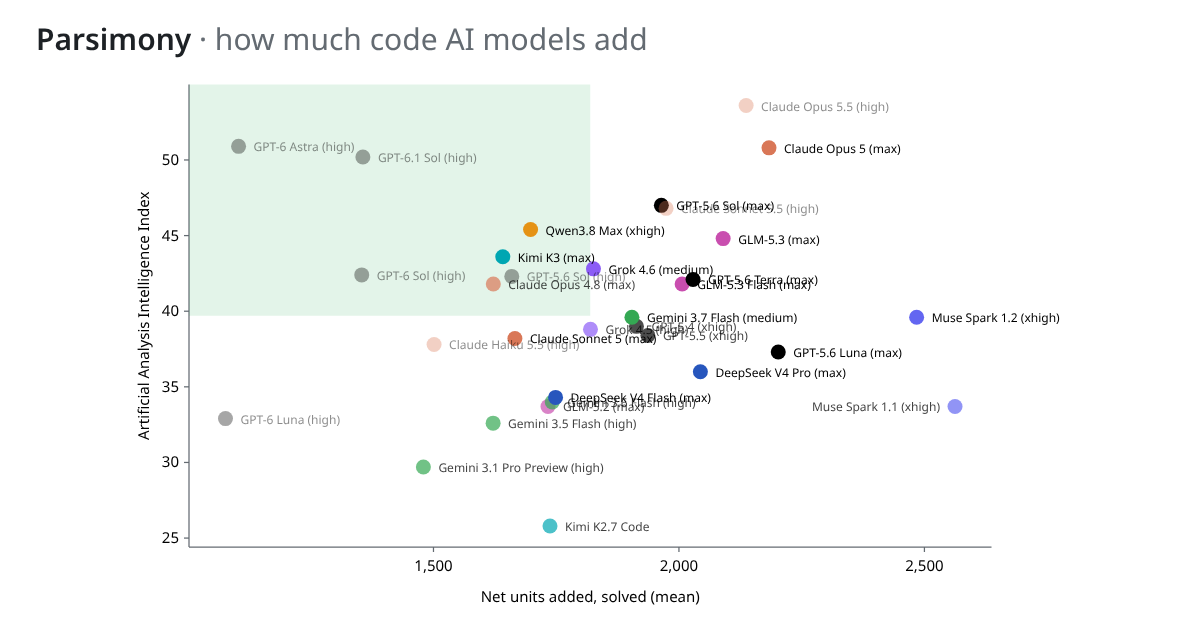
Existing benchmarks measure solve rate and token output/cost, but don't punish excess code, which makes a codebase harder to work with in the long term. I wanted to measure this since it matters most for long-term projects.Method: it takes the patches that benchmarks already publish (DeepSWE, SWE-bench Verified, SWE-bench Live) and counts "coding units": syntax elements like statements, calls, names and literals. I didn't use lines of code, so cramming code isn't rewarded. Deleted code is subtracted, so it measures net units.GPT-6 and Claude 5.5 have no public patches yet, so I ran them myself on 3–10 tasks on my own subscriptions (shown as faded circles, not ranked).Any feedback or model contributions are welcome, especially public patch exports for newer models.GitHub: https://github.com/La5u/ParsimonyNot affiliated with any of the benchmarks.
Comments (1)
finally, a coding agent that actually cares about keeping things tidy. how does it compare to others on ease of use?
Related Products
Free Currency Converter API
Limestone Digital
AI-Powered Software Development, Engineering Team Augmentation,
ChangeSpec
Free Mermaid Live Editor & Diagram Maker
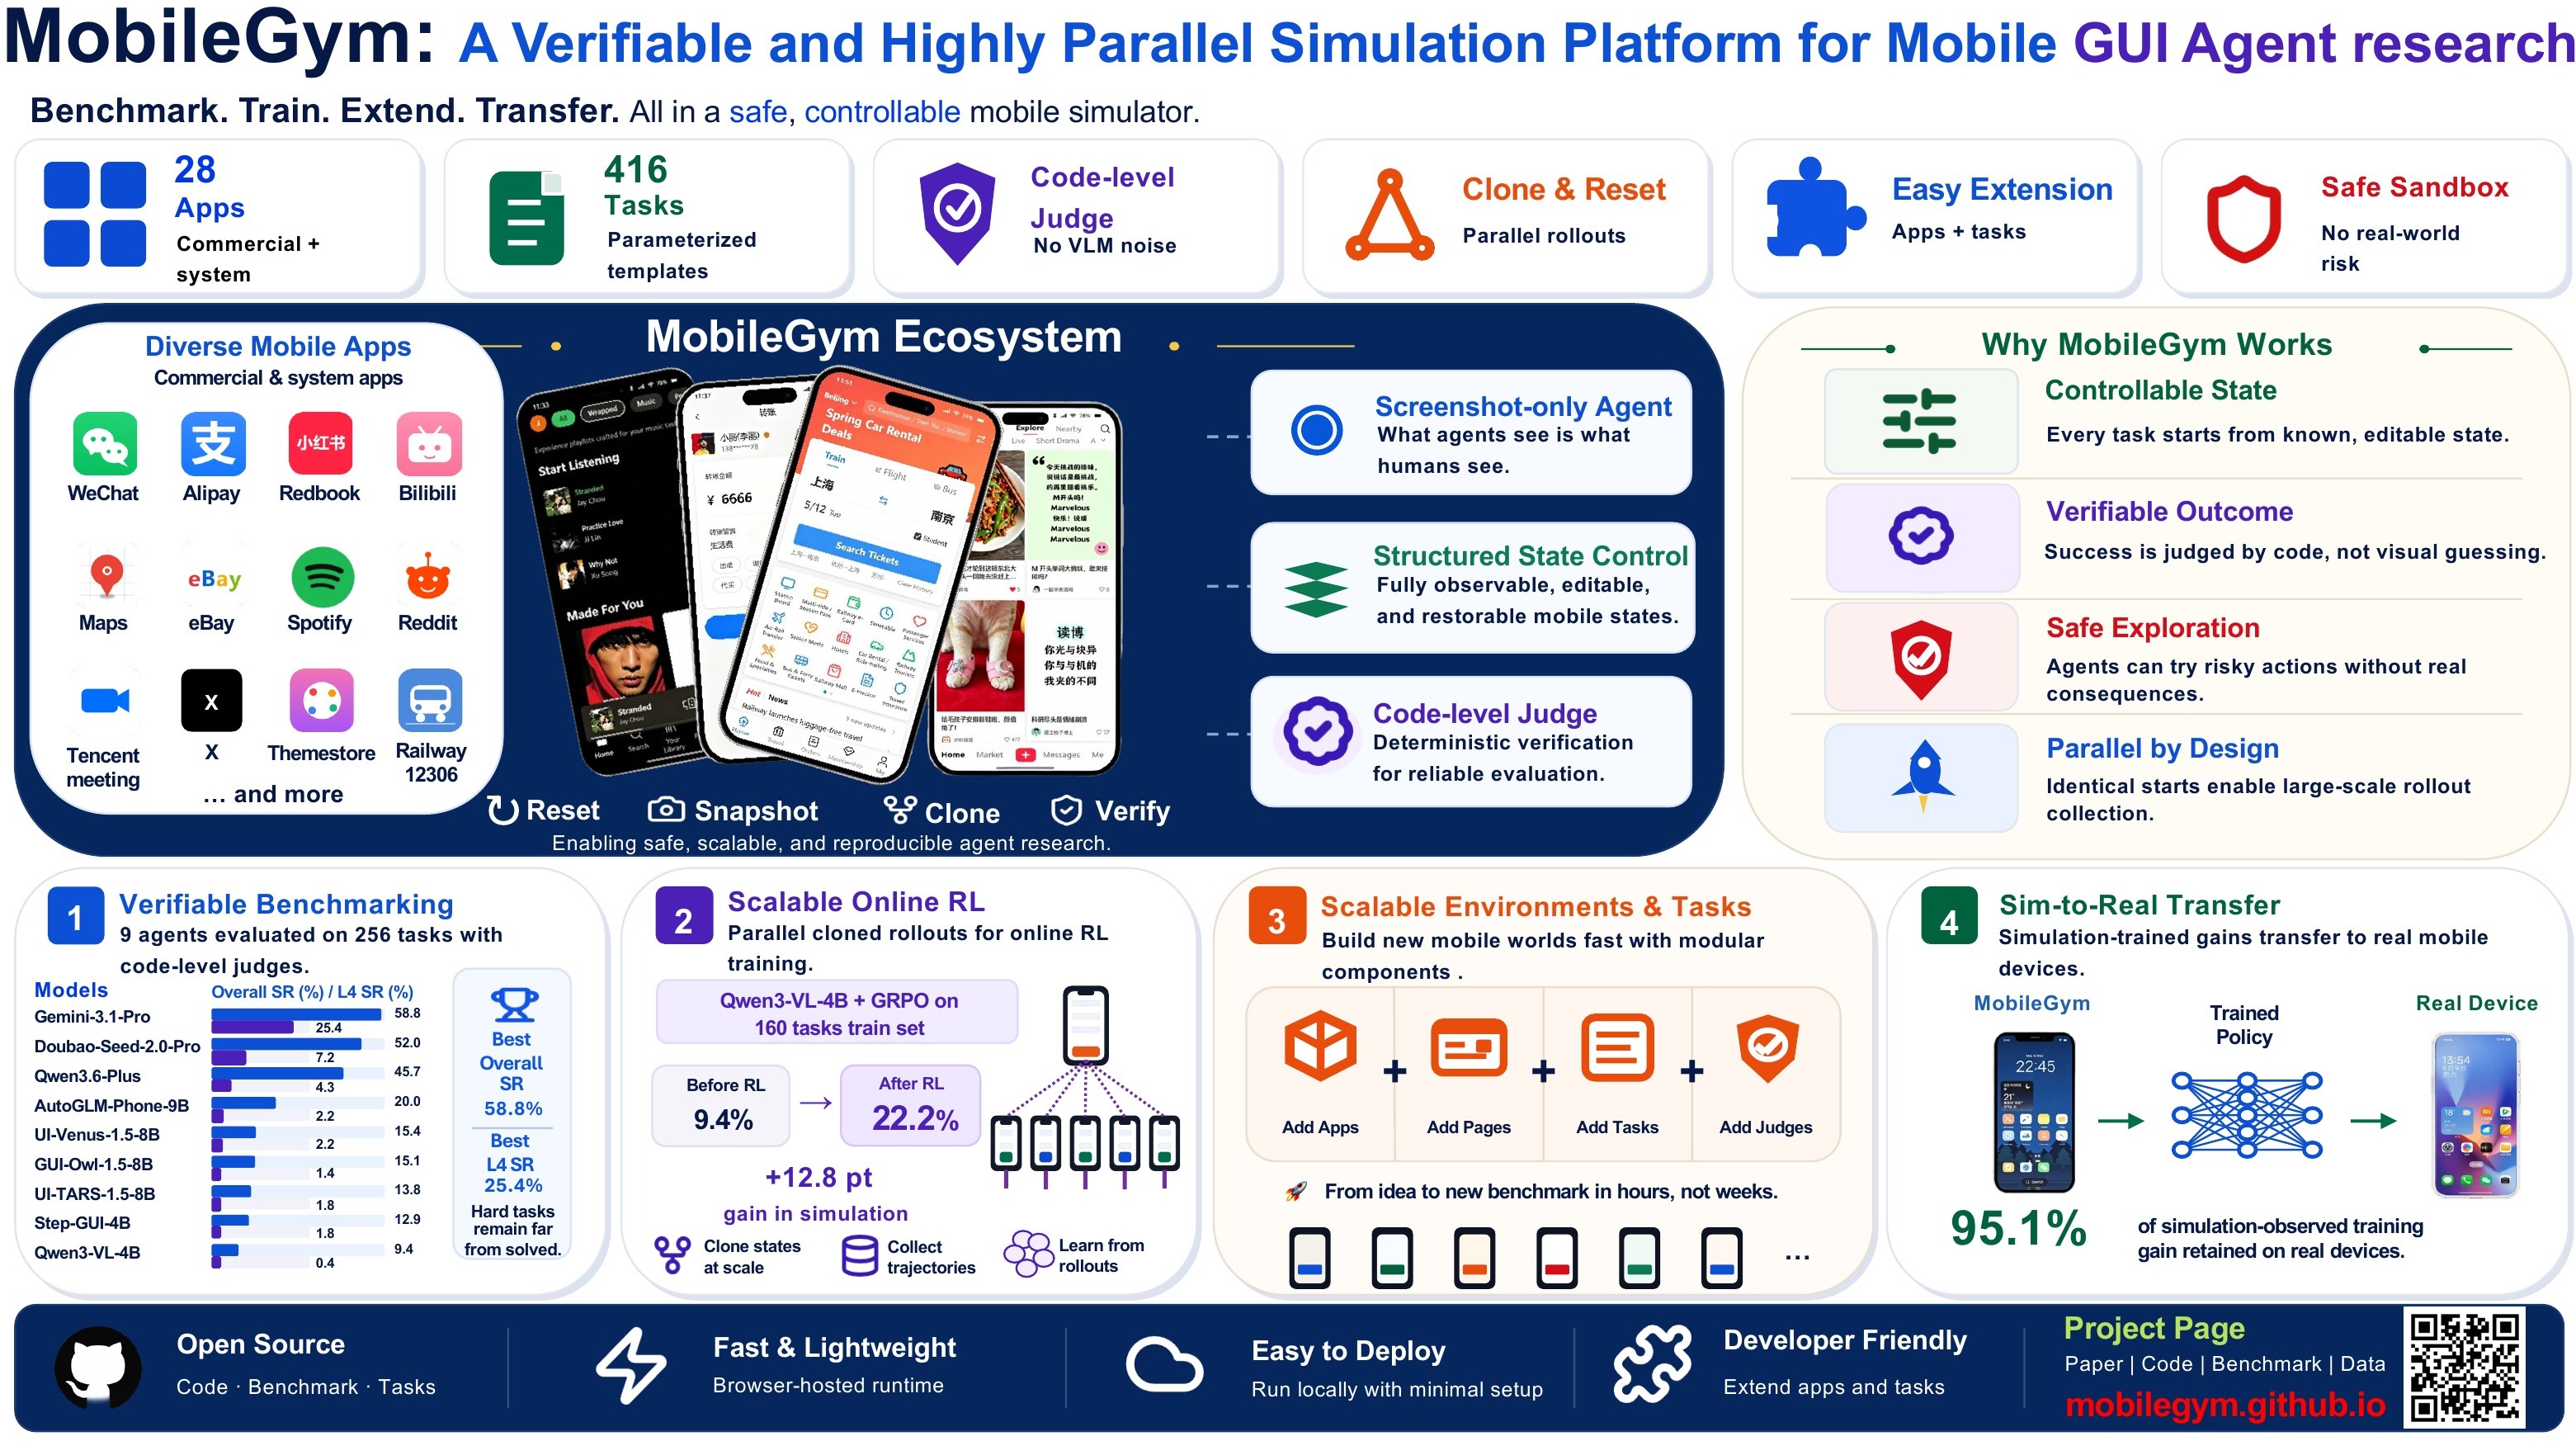
MobileGym: A Verifiable and Highly Parallel Simulation Platform for Mobile GUI A

Universal Data Workbench
A thorough tool for cleaning, validating, and converting JSON, CSV, and more.